Featured
About This Project
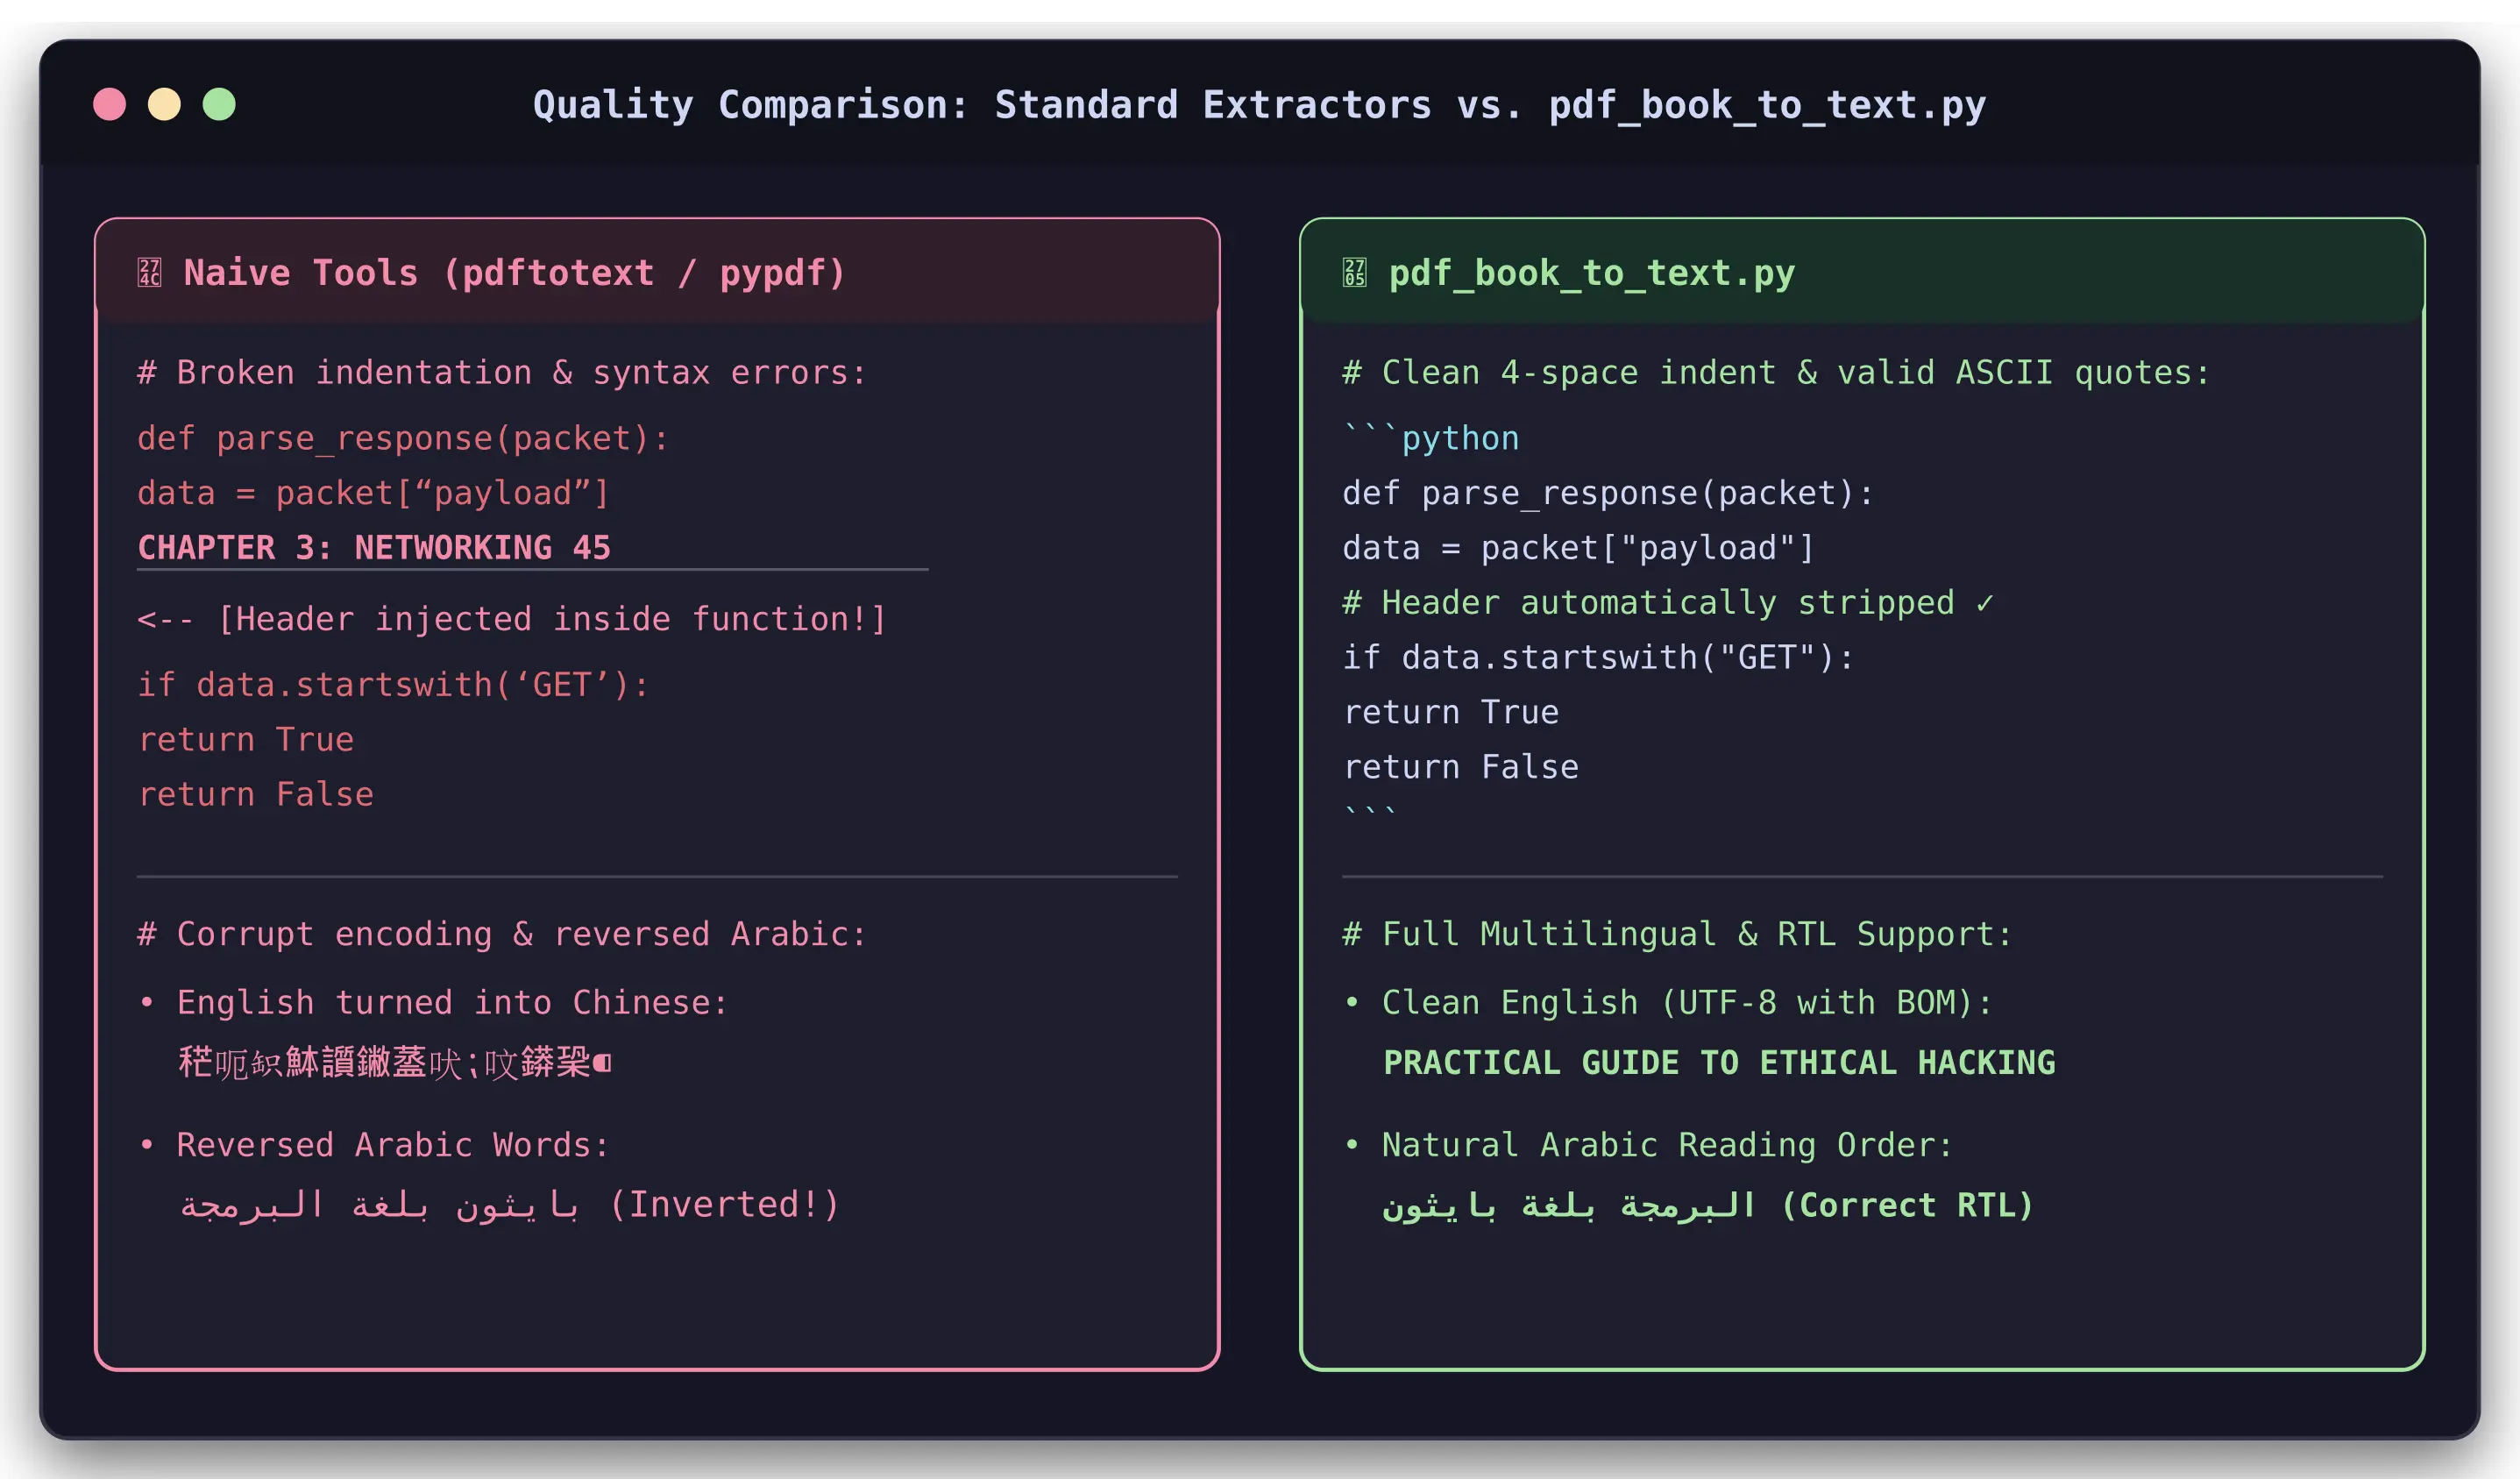
Standard PDF extraction tools (pdftotext, pypdf, pdfplumber) treat technical books like plain text documents. This breaks code listings, loses indentation, inserts running headers into functions, and destroys chapter hierarchies.
###FEATURES:
Authoritative Chapter Hierarchy: Uses PDF bookmarks (Table of Contents) as ground truth, formatting headings with clean underlines (====, ----, ~~~~).
Preserves Section Numbers: Retains printed numbering (3.1 Function calls, 3.2 Math functions) that typical outline parsers drop.
Dual-Tier Monospace & Code Detection:
Regex matching for popular monospace families (Courier, Consolas, JetBrains Mono, Fira Code, M+, DejaVu, etc.).
Mathematical character-metric analysis: Measures Latin glyph width variance. If character advances are uniform across diverse letters ('i' vs 'm'), it is classified as code—detecting custom/renamed fonts with 100% accuracy.
Intelligent Indentation Reconstruction: Computes code indentation and multi-column alignment from character bounding boxes, keeping tabs, nested loops, and ASCII diagrams aligned.
Margin Band Header/Footer Removal: Detects recurring top and bottom margin coordinates across hundreds of pages, removing page numbers and alternating chapter headers without losing text.
Continuous Code Stitching: Re-joins code blocks that span across physical page breaks.
Syntax Normalization: Straightens curly quotes (“, ”, ‘, ’) and hyphens (−, —) into valid ASCII code characters (", ', -).
Smart De-Hyphenation: Reconstructs broken lines while checking an internal book-specific vocabulary to preserve true compound words.
Full Multilingual & Arabic (RTL) Support: Preserves natural Right-to-Left (RTL) reading order and span continuity for Arabic, Hebrew, and Persian PDFs without word inversion.
Mojibake & Encoding Immunity: Sanitizes corrupt PDF bookmarks (null bytes, byte-swapped UTF-16) and outputs UTF-8 with BOM (utf-8-sig), completely preventing text editors (like Windows Notepad) from misinterpreting English/Arabic as Chinese characters.
Chapter Splitting (--split-chapters): Exports both the full text and a folder of numbered chapter files (01 - Preface.txt, 02 - Chapter 1.txt).
LLM & RAG Friendly: Optional single-line paragraph mode (-w 0) with page markers (--page-markers) for vector databases and embedding pipelines.